What’s New: Edit live studies, run frame specific video evals and more
From live study editing to more precise video evaluation tooling, October’s updates let you run smarter research with our trusted participant Network. Read through to check out what’s new.
Fix live studies without disrupting data collection
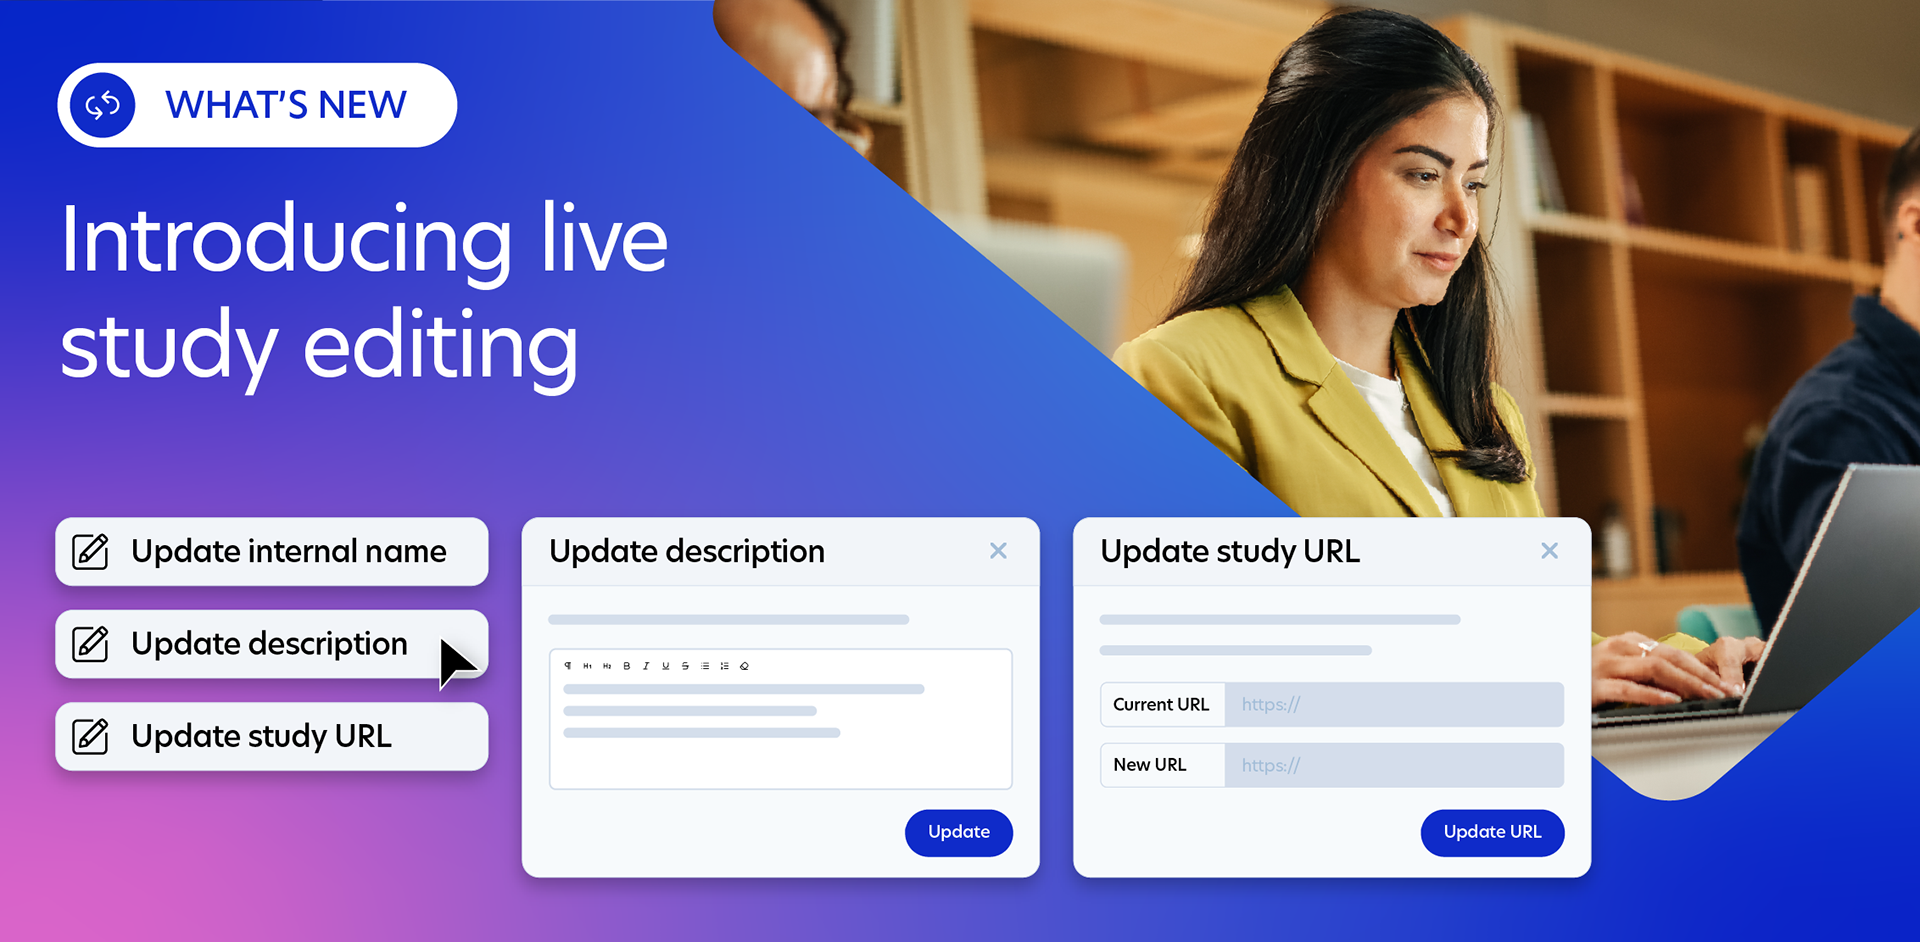
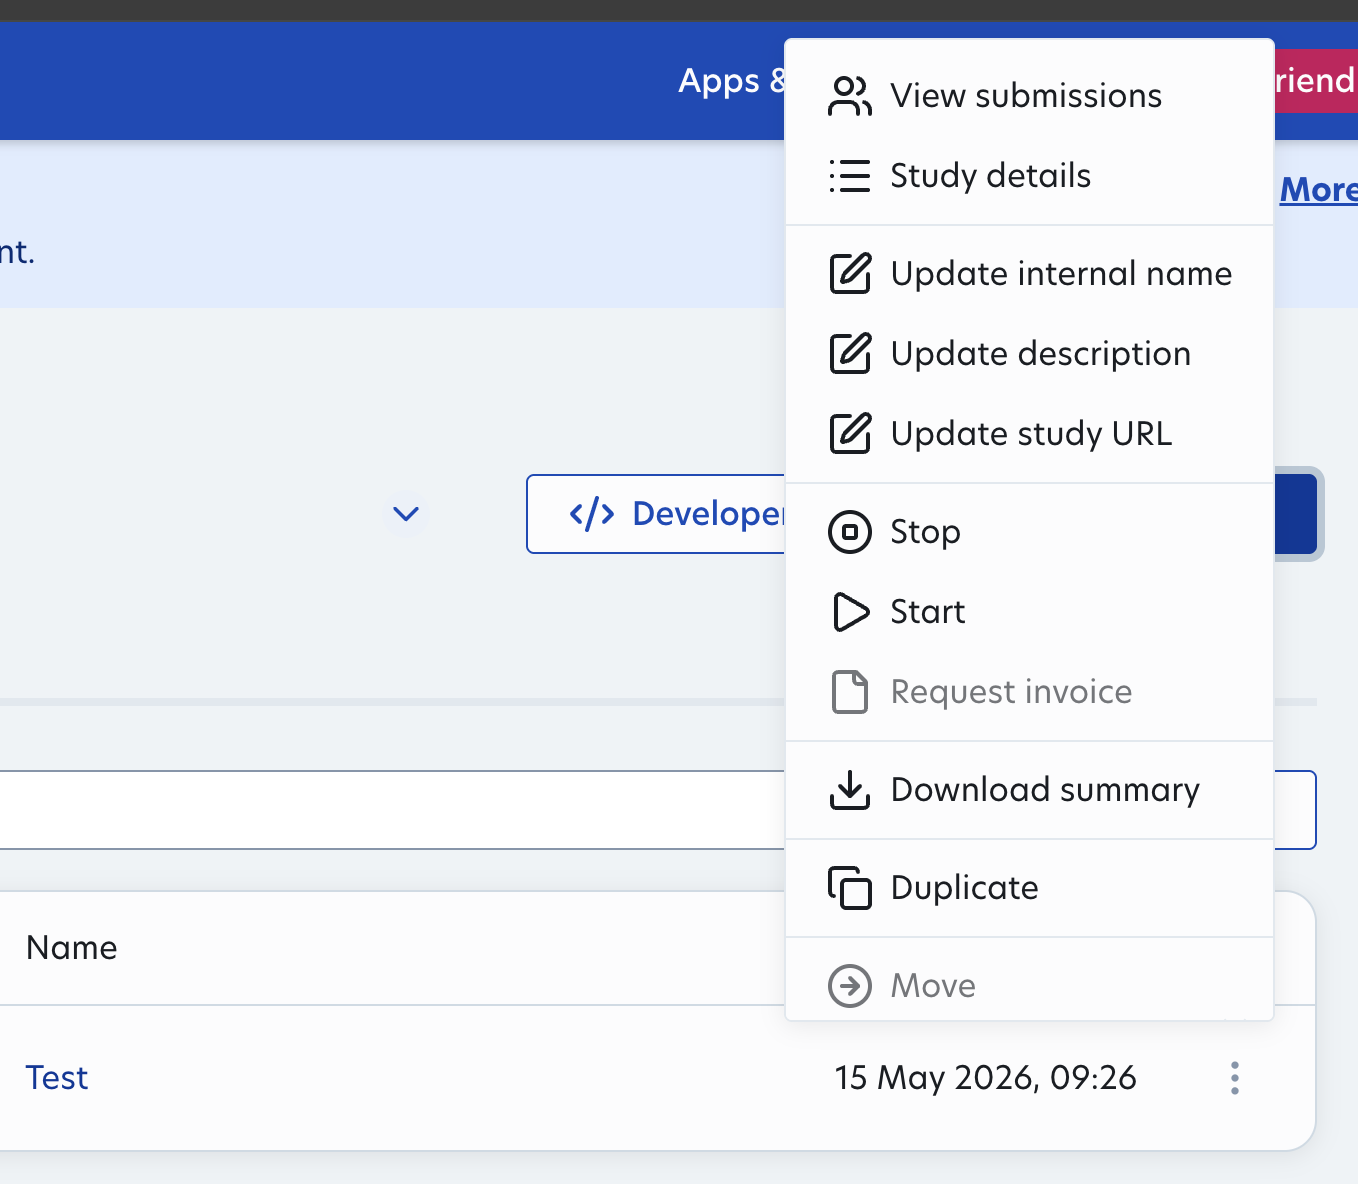
When you notice errors in your study, the time taken to stop, duplicate, fix and launch, delays your data collection. If you or your participants spot an error while your study is live, in the UI and API you can now edit:
- Descriptions
- Study links
- Content warnings
When you edit these fields, participants who haven’t completed your study yet will see the updated version. This gives you greater control, without compromising your time to data.
Narrate video segments and pin feedback to exact frames
Now with all modalities available in AI Task Builder and almost 10,000 video studies run on Prolific in the last 3 months alone, video evaluations just got better.
Video narration
If your task needs specific sections of a video narrated without a length restriction, this new feature is for you.
Participants can mark a time span on the video, and narrate that specific section. They can narrate multiple sections per individual video, plus participants can edit and re-record a specific audio clip as they need to.
You get one JSON file back, which maps each audio clip to the video range so your collection is clearly structured for analysis.
Frame controls
If you need participants to spot errors or identify inconsistencies, you need that feedback tied to specific points in your video. With frame specific controls, our video player now includes a live frame counter. When your evaluation needs this kind of precision, you can turn this feature on so it only shows for the tasks that need it.
Get started
Both features are available via the API and CLI, so you can drop them straight into your pipeline.
Not sure where to start? Talk to our team and we'll set your first video study up with you.
LLM and Bot authenticity checks are available on Pavlovia and LimeSurvey
Earlier this year, we launched Bot authenticity checks on Qualtrics. Since then, we’ve checked 6M+ responses, with just 0.05% flagged, proof our detection holds at scale. These checks are one layer of Protocol, our multi-layered data quality system.
Now live on Pavlovia and LimeSurvey. You can enable either or both:
- LLM checks: Catch AI-generated free-text responses, 98.7% precision
- Bot checks: Catch AI agents on any question type, 100% accuracy in testing
Backed by our 100% Human Guarantee, so if a submission is flagged non-human by Bot checks, you’ll get double the cost back as Prolific credits.
Find out more by viewing the step-by-step integration guides for Pavlovia, LimeSurvey and Qualtrics.
On AI Task Builder, LLM and Bot checks are on by default for every study.
New features for smarter study setup
Ranked filter search now in the API
With over 300 behavioural and consumer filters available, how you search and apply the right ones can be time consuming. For API users, instead of pulling the entire filter list you can now use three endpoints for smoother search and discovery:
GET /filters/search/?q=searches across filter titles, questions, descriptions, categories, IDs and choice labels. It returns ranked matches, each with up to three matching choices.GET /filters/{id}/choices/search/?q=searches inside one filter's choices (e.g. a country list), ranked and paginatedGET /filters/{id}/choices/browses a filter's choices in catalogue order, paginated
Explore in the API now.
Exclude participants based on previous submission status
The ‘Exclude from previous studies filter’ now lets you choose specific submissions statuses. This means that for example, if you want to exclude participants who were screened out of your previous study, but not those who were approved, you can now set your exact requirements with the updated functionality. Available in the API and app.
Set screen-out caps on multi-submission studies
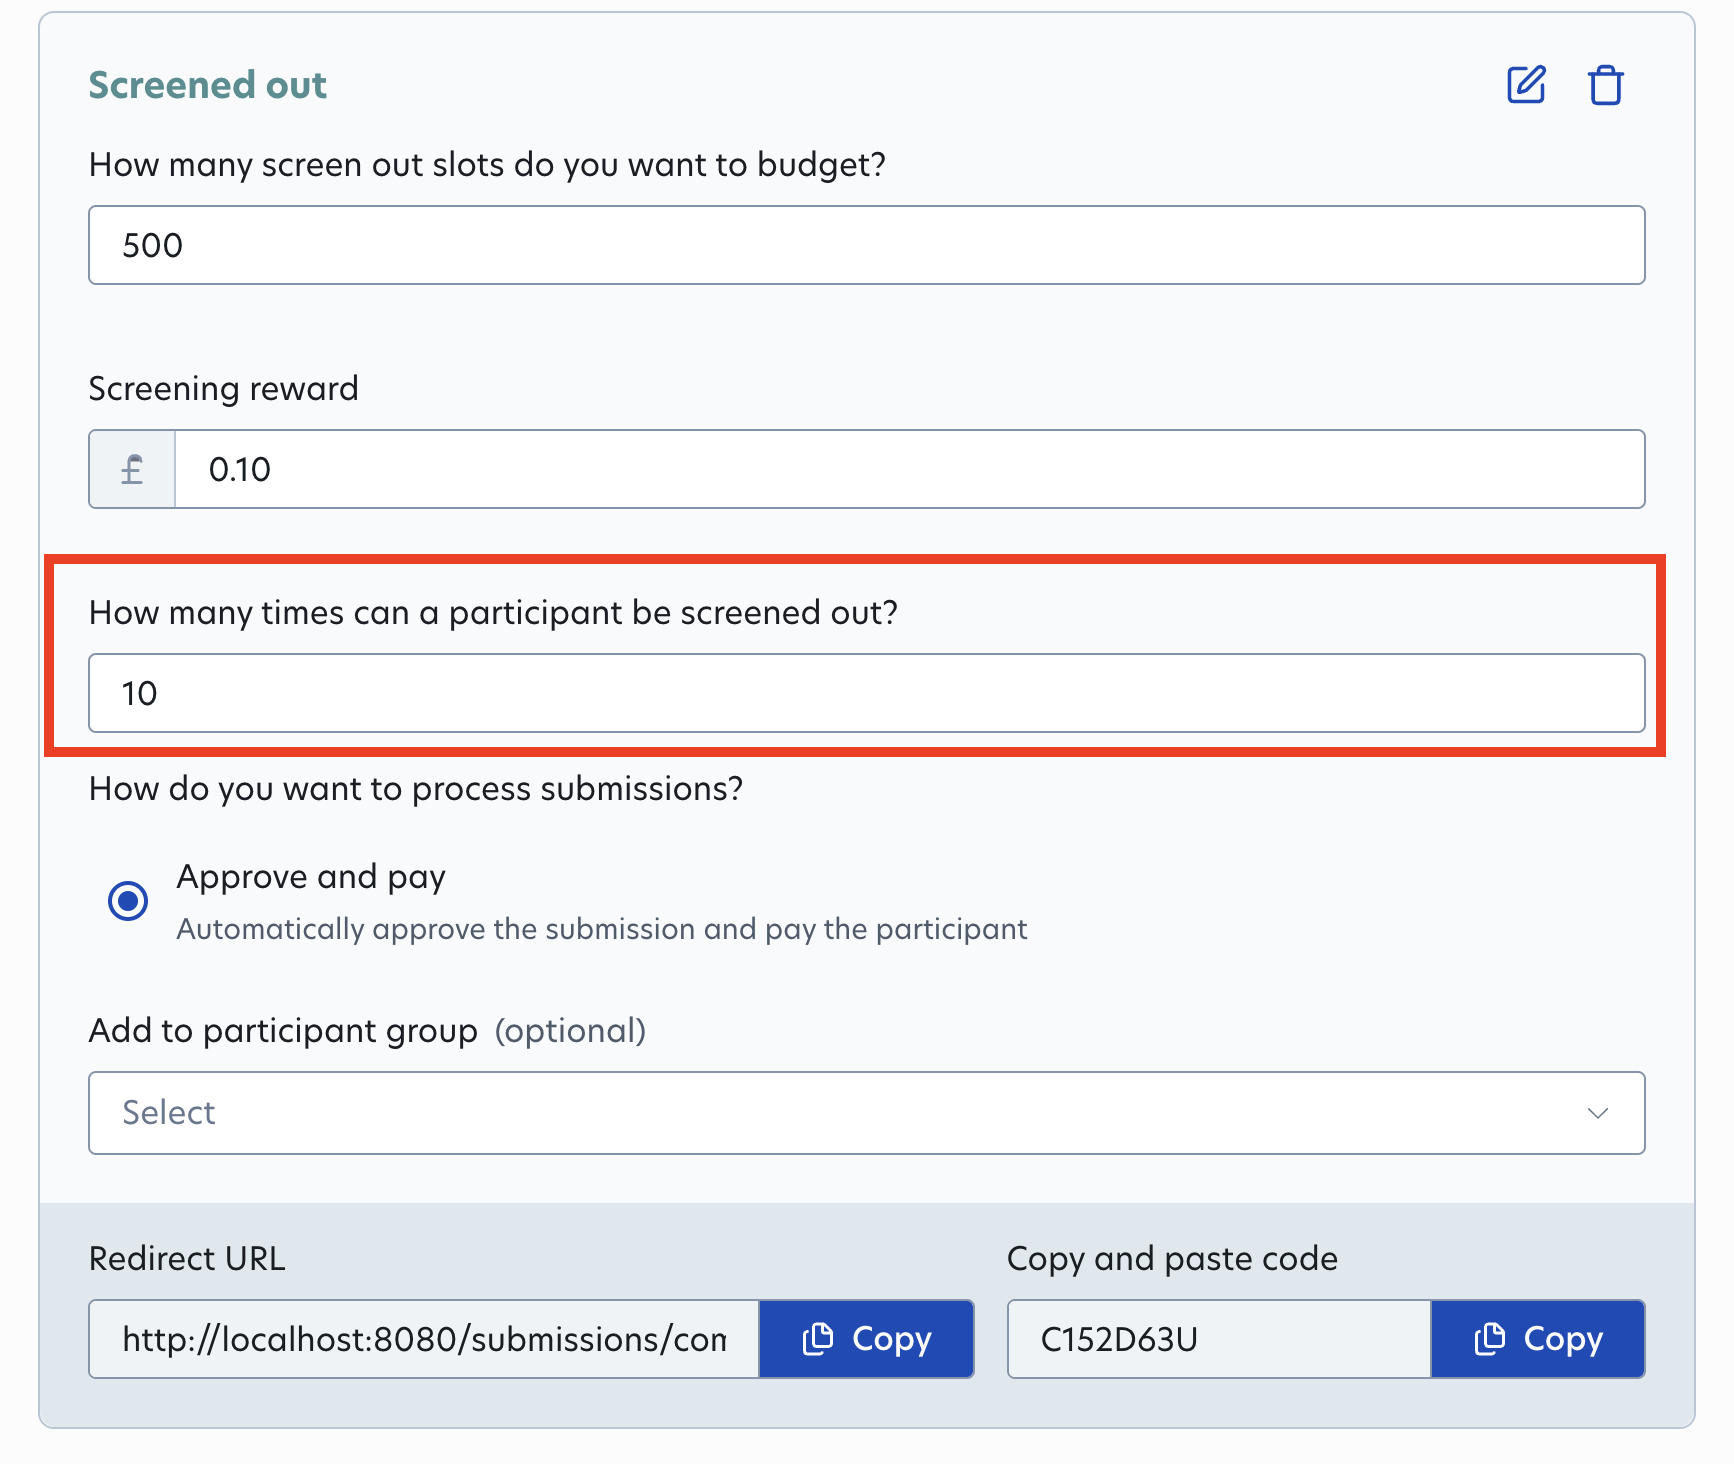
Avoid repeat screen-outs with a new cap that lets you define the number of times a participant can be screened out of your study. Once a participant reaches the cap, they’ll no longer be eligible and their next submission attempt gets rejected. It’s an optional setting, available in the API and app.
Over 110,000 participants with verified expertise
Expert recruitment is now one of the fastest growing ways researchers use Prolific. So far this year, studies targeting our verified Expert groups have filled more than 250,000 study places.
How researchers use our Experts
- AI model evaluation and training data: AI Taskers rate, rank and write responses that need real reasoning skill. More than 13,000 participants belong to this cohort, verified for skills across comparative reasoning, fact checking, audio annotation and more.
- Language and localisation studies: Our most active group saw 1,850+ new participants assessed this month alone, taking the total to 18,400+. Filter for a specific language, or work with our team for niche dialects and requirements.
- Healthcare and clinical research: 2,200+ verified healthcare professionals, including specialist doctors, GPs, nurses, pharmacists, dentists and mental health professionals. Use them for clinical judgement tasks, medical content review or practitioner surveys.
- STEM, finance and coding: Growing segments with deep expertise for specialist evaluation, such as verified programmers.
Expertise is verified for the specific skills or credential before the participant can join a group. Target the group directly and you'll reach people who already qualify.
Find them in-app under Participants > Add screeners > Domain Experts. To find them under the API, take a look here.
HUMAINE for Health
Health is one of the biggest topics in AI, making up 14.7% of conversations in our HUMAINE study. So we asked 100 verified clinicians to review how six frontier models handle health conversations, and compared their verdicts with the public’s preferences and with AI judges. Early pilot findings:
- Public preference isn’t a safety signal. When one reply had a flagged clinical problem, the public still picked it 46% of the time. Clinicians picked it 19% of the time.
- AI judges need checking against clinicians. On the same conversations, the clinician panel flagged serious errors in 26%. Two frontier models given the clinicians’ questionnaire word for word flagged 25% and 74%.
- Failures surface under pressure. Models that answered safely at first gave way after a few turns of pushback. A first-reply test would miss this.
The clinicians come from our verified healthcare Network. Every clinician’s credentials are checked against professional registries, and each has a performance record.
Read the method and early findings, or talk to our team about your clinical research.
Listen: Episode 2 of the Signal podcast
Will digital twins ever replace human participants?
Can an AI trained to mimic you predict how you’d respond to a survey? In episode 2, Prolific’s Head of Polling, Oriol Bosch Jover, talks with Olivier Toubia (Columbia Business School, co-head of the Digital Twins Lab) and Beca Almeida (founder, Doppel Market). Together they unpack what digital twins and synthetic respondents can and can’t do in research today.
Listen to the latest episode here.
Webinar: Digital Twins. How accurate are they, and what is the sentiment of the participants behind them?
Synthetic respondents and digital twins are becoming a faster, cheaper alternative to live participants. But does the data hold up, and what do the people being modelled think about it?
Join Andrew Gordon, Head of Research Sciences on November 4th as Prolific presents two new studies exploring the accuracy of synthetic respondents and how people feel about having a digital twin of themselves.
Register here.
Connect with us in person
20 Nov: NBA x AI Research: Brooklyn Nets vs. Orlando Magic
Join us at a luxury box suite to watch the Brooklyn Mets take on the Orlando Magic at the Barclay’s Center. It’s an exclusive event for AI leaders to discuss model impact on high performance fields, especially as methods advance. Registration is subject to approval, request your spot here.
That's all for our October update! See you next month.
The Prolific team